Apache Kafka Explained: Topics, Partitions, Consumer Groups, and Your First Event Pipeline
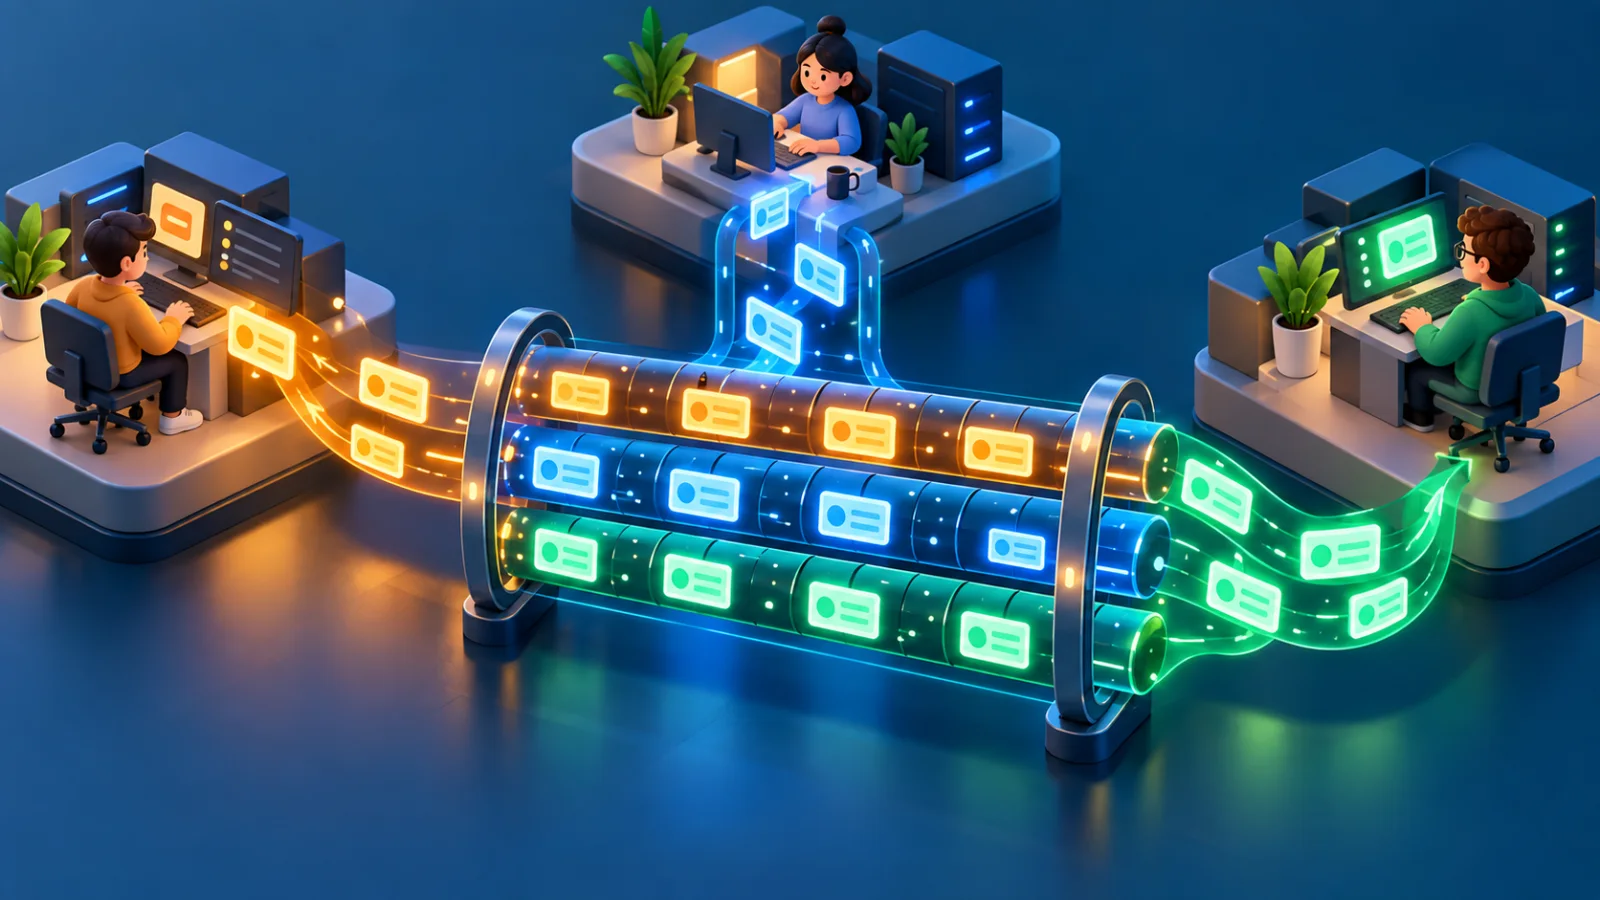
Follow one order event from producer to consumers, then run a local Kafka topic and learn what partitions, offsets, keys, and consumer groups actually do.
A queue is often described as a place to put work for later. Kafka can do that, but the more useful mental model is an append-only event log that multiple applications can read independently. An order service records that an order was placed. Inventory, analytics, and notifications can each react at their own pace without the order service calling all three synchronously.
That promise comes with design decisions: which events belong together, what key determines their order, how long records remain available, and what happens when a consumer fails. This tutorial follows one event through Kafka and gives you a local exercise before exploring the tradeoffs.
The five nouns you need first
A producer writes a record. A topic names a stream of related records. A topic has one or more partitions, each an ordered log. A broker stores partitions and serves client requests. A consumer reads records; consumers in the same group divide partitions among themselves.
Each record has a value, an optional key, headers, and a timestamp. Kafka assigns an offset within the partition. The pair (topic, partition, offset) locates a record. Offset 42 in partition 0 has no ordering relationship with offset 42 in partition 1.
Imagine topic orders.placed.v1 with four partitions. Publish records keyed by orderId. The same order ID maps to the same partition under a stable partitioning scheme, so its related events can be processed in partition order. Kafka guarantees order within a partition, not a single total order across the topic. If you later change partition counts, key placement for future records may change; evaluate that before relying on long-lived per-key sequencing.
A concrete event contract
Our order service publishes an event after an order is committed:
{
  "eventId": "evt_01JQ8X8F",
  "eventType": "OrderPlaced",
  "schemaVersion": 1,
  "occurredAt": "2026-09-29T10:30:00Z",
  "orderId": "ord_782",
  "customerId": "cus_17",
  "totalMinor": 12900,
  "currency": "USD"
}
Use orderId as the Kafka record key. eventId identifies this occurrence for duplicate detection. totalMinor expresses money in the smallest currency unit so consumers do not infer floating-point behavior. Decide whether customer data is needed at all; event streams can be retained and replayed, so unnecessary personal data creates long-lived exposure.
An event should report a fact that already happened, such as OrderPlaced, rather than a command disguised as a fact. A separate command like ReserveInventory has a different owner and failure contract. Keep producer and consumer teams aligned on the meaning of each field, including whether an order can be cancelled later and which event reports that change.
What happens when the event is written?
The producer connects to the cluster, obtains topic metadata, selects a partition, and sends the record to its leader broker. Replicas can maintain copies on other brokers. The producer's acknowledgement settings affect when it considers the send successful. Kafka appends the record; consumers fetch it from their assigned partitions.
A consumer group stores its progress as committed offsets. Committing an offset means the group says it has reached a position; it does not delete the record from the topic. Another group can read the same record, and a group can deliberately reset its position to replay retained events. Retention is controlled by topic settings, independently of whether a particular consumer has read the data.
For example, inventory-reservation and sales-analytics are two group IDs. Both see OrderPlaced. If you run three inventory consumer instances against four partitions, assignments divide those partitions among the three. A fourth instance may use the remaining capacity; a fifth in that group cannot gain a partition from this topic alone. Different groups are independent subscribers.
When a consumer joins, leaves, or fails, the group may rebalance and redistribute partitions. The application must handle this without losing uncommitted work or processing a side effect twice. This is why consumer code should not assume it owns one partition forever.
Run Kafka locally
The current Apache Kafka quickstart offers both a binary route and an official Docker image. For a local experiment, its Docker command starts Kafka on port 9092:
docker run -d --name kafka-demo -p 9092:9092 apache/kafka:4.3.1
Use the CLI tools from the Kafka distribution (or within an environment containing them). The commands below match the official quickstart structure; run them where bin/ exists and the broker is reachable as localhost:9092:
bin/kafka-topics.sh --create --topic quickstart-events \
  --bootstrap-server localhost:9092

bin/kafka-topics.sh --describe --topic quickstart-events \
  --bootstrap-server localhost:9092

bin/kafka-console-producer.sh --topic quickstart-events \
  --bootstrap-server localhost:9092
Type a few lines into the producer and press Enter after each. In another terminal, read them:
bin/kafka-console-consumer.sh --topic quickstart-events \
  --from-beginning --bootstrap-server localhost:9092
This is a local learning setup with a single broker, not a production deployment. If your CLI runs inside the container, use its bundled binaries and local broker address instead of assuming your host has Kafka installed. Stop the demo container when finished with docker stop kafka-demo; remove it only if you no longer need its local data.
Now repeat with two consumers in the same group and observe how records are assigned. Start another consumer with a different group and note that it gets its own progress. Use a multi-partition test topic to see meaningful parallelism; a one-partition topic can have only one actively assigned consumer per group for that topic.
Partition keys are a business decision
If all events for an order must preserve order, key by order ID. If you key every record with a constant string, one partition becomes hot and you lose parallelism. If you use a random key, related records may land in different partitions and lose per-order ordering.
A good key has enough variety for distribution and matches the entity whose event order matters. There is no universal choice: customerId preserves per-customer order but can create a hot customer; orderId distributes orders but does not order all events for one customer. Write down the required ordering scope before choosing the key.
Partition count sets an upper bound on parallel consumer instances for a single group reading that topic. More partitions also mean more metadata, open files, replication work, and operational overhead. Start with a measured workload and growth expectation. Do not pick a huge count simply because Kafka is distributed.
Retention, replay, and compaction
Kafka does not erase a record just because a consumer reads it. With time- or size-based retention, old records eventually leave the log. A consumer that is offline longer than retention may be unable to resume from its old offset. Monitor this risk.
Log compaction is different: for a compacted topic, Kafka keeps a recent value for each key over time, subject to compaction behavior. It suits state snapshots such as customer-preferences, not a complete immutable audit history. A tombstone is a record with a key and null value used to represent deletion in compacted streams. Decide whether your topic is an event history, a state changelog, or both through separate topics; the retention policy follows that purpose.
Replay can rebuild a projection or repair a consumer, but it can also repeat side effects. Replaying analytics calculations is usually manageable. Replaying “send welcome email” without deduplication is not. Keep eventId, make external effects idempotent, and distinguish rebuilding state from sending a new notification.
Kafka and a traditional job queue
A conventional job queue is often enough for “run this background job once soon.” Kafka is useful when several independent consumers need the same durable stream, when replay matters, or when a high-throughput event pipeline is justified. It brings broker operations, schema governance, partition design, and consumer monitoring. Do not add it to a small app solely to move one email job off the request thread.
Kafka Connect can move data between Kafka and external systems, while Kafka Streams offers stateful stream processing for Java and Scala applications. Both are useful after the producer, topic, and consumer model is clear. They are not prerequisites for the first event pipeline.
Your first project
Create orders.placed.v1 with a few partitions in a disposable development environment. Publish sample JSON with orderId as key, run separate inventory and analytics groups, and record what happens when you stop and restart one consumer. Then answer four questions in your project README:
- Which entity needs ordering, and why is that the key?
- How does each group know where to resume?
- How long can a consumer be offline before retention becomes a problem?
- What does a repeated event do to each side effect?
If you can answer those questions while watching the local pipeline, you understand the core of Kafka far better than someone who has only memorized a diagram.
Official references
Featured Articles
Kafka in Production: Partition Strategy, Consumer Lag, Reliability, and an Incident Playbook
A production Kafka cluster needs more than brokers. Learn to choose partition keys, plan retention and capacity, monitor lag, handle rebalances, and rehearse failure recovery.
Laravel and Kafka Without Lost Events: The Transactional Outbox, Idempotent Consumers, and PostgreSQL
A database commit and a Kafka publish cannot safely be treated as one ordinary transaction. This guide builds an outbox and consumer design that survives crashes and duplicate delivery.
How to Design APIs That Clients Can Trust: A Practical Contract-First Guide
Good APIs make the next client request predictable. Design an enrollment API from the use case outward, with clear contracts, safe retries, useful errors, and a plan for change.
Comments
0 commentsNo approved comments are visible yet. New community replies may wait for moderation.