Kostenloses Buch
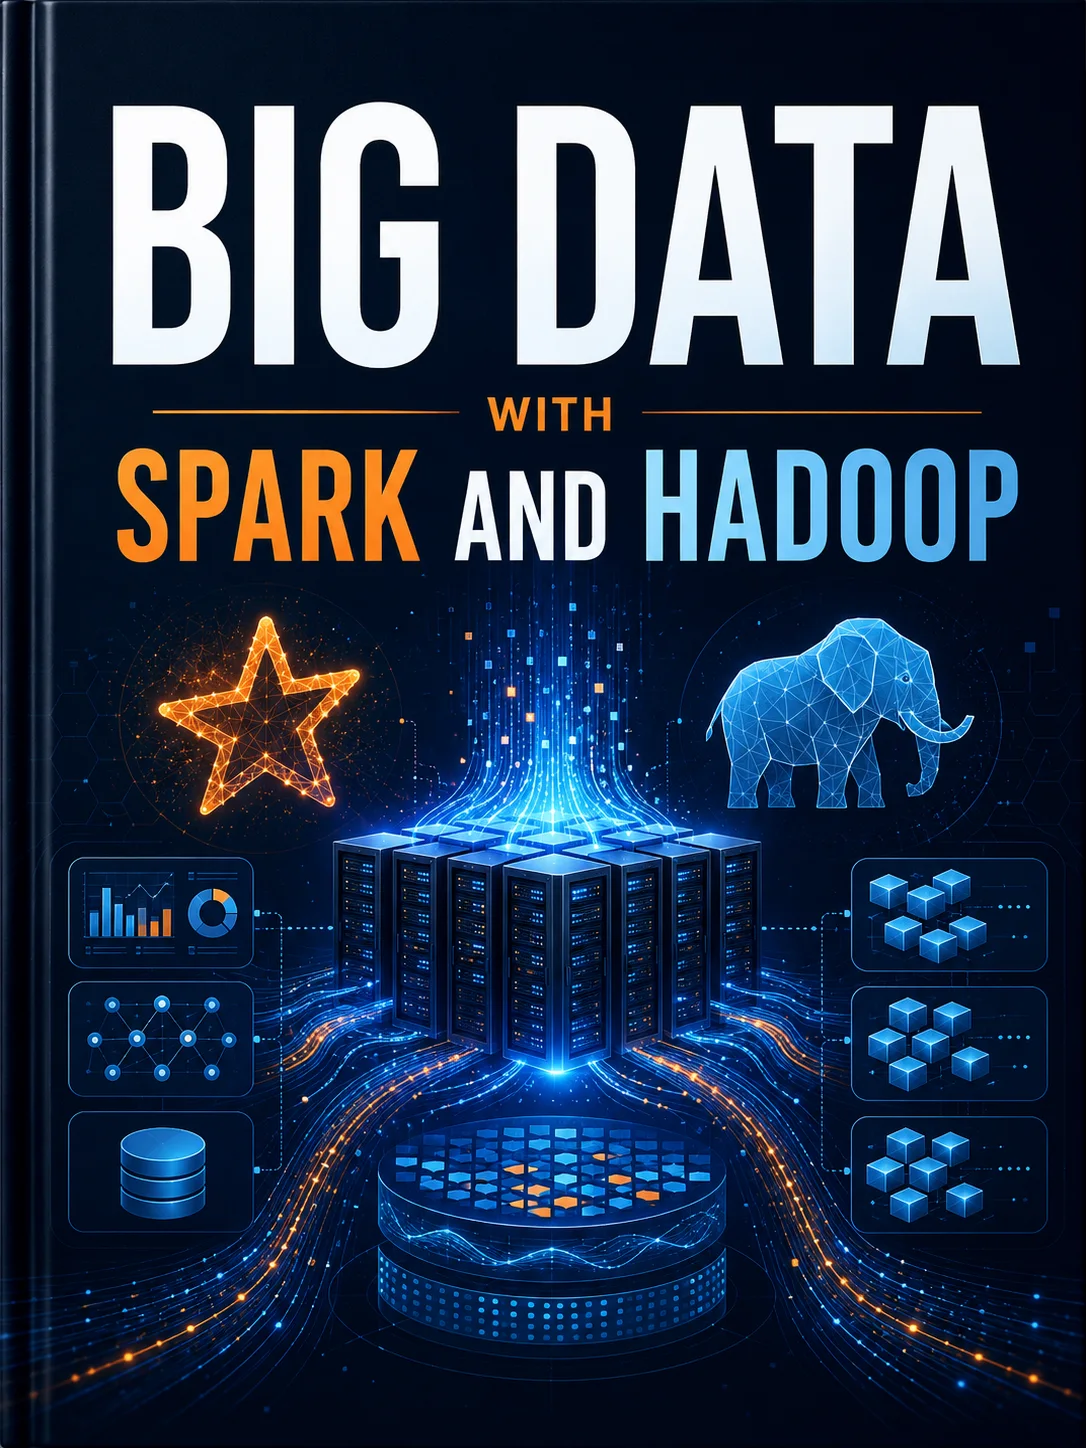
Big Data mit Spark und Hadoop
Lesezugriff
Kostenloses Buch
Dieses Buch vermittelt Big-Data-Systeme in einfacher Sprache vom Anfänger bis zum praktischen Plattformdesign. Es umfasst Hadoop, Spark, verteilte Verarbeitung, Data Lakes, Optimierung, Überwachung und reale Datenpipelinemuster.
Level: intermediateSprache: DE DeutschBewertung: 0Rezensionen: 0
Buch
Book contents
01Chapter 1: Introduction to Big Data Systems02Chapter 2: Batch Processing and Distributed Storage03Chapter 3: Hadoop Foundations and HDFS04Chapter 4: MapReduce and Cluster Thinking05Chapter 5: Spark Fundamentals and Execution Model06Chapter 6: PySpark for Practical Data Processing07Chapter 7: Data Lakes, File Formats, and Partitioning08Chapter 8: Resource Management and Scheduling09Chapter 9: ETL Pipelines at Scale10Chapter 10: Performance Tuning for Spark Jobs11Chapter 11: Monitoring and Debugging Big Data Workloads12Chapter 12: Security and Governance in Data Platforms13Chapter 13: Streaming and Near-Real-Time Extensions14Chapter 14: Cost Optimization in Data Processing15Chapter 15: Capstone: Build a Spark Data Pipeline16Chapter 16: Capstone: Operate a Hadoop and Spark Stack17Appendix A: Commands and Workflow Cheat Sheet18Appendix B: Reference Architectures and Patterns19Appendix C: Common Mistakes and Fixes20Appendix D: Best Practices Summary
Rezensionen
Noch keine freigegebenen Rezensionen sichtbar.
Empfohlene Bücher
Diskussion
0 KommentareNoch keine freigegebenen Kommentare sichtbar. Neue Antworten können moderiert werden.